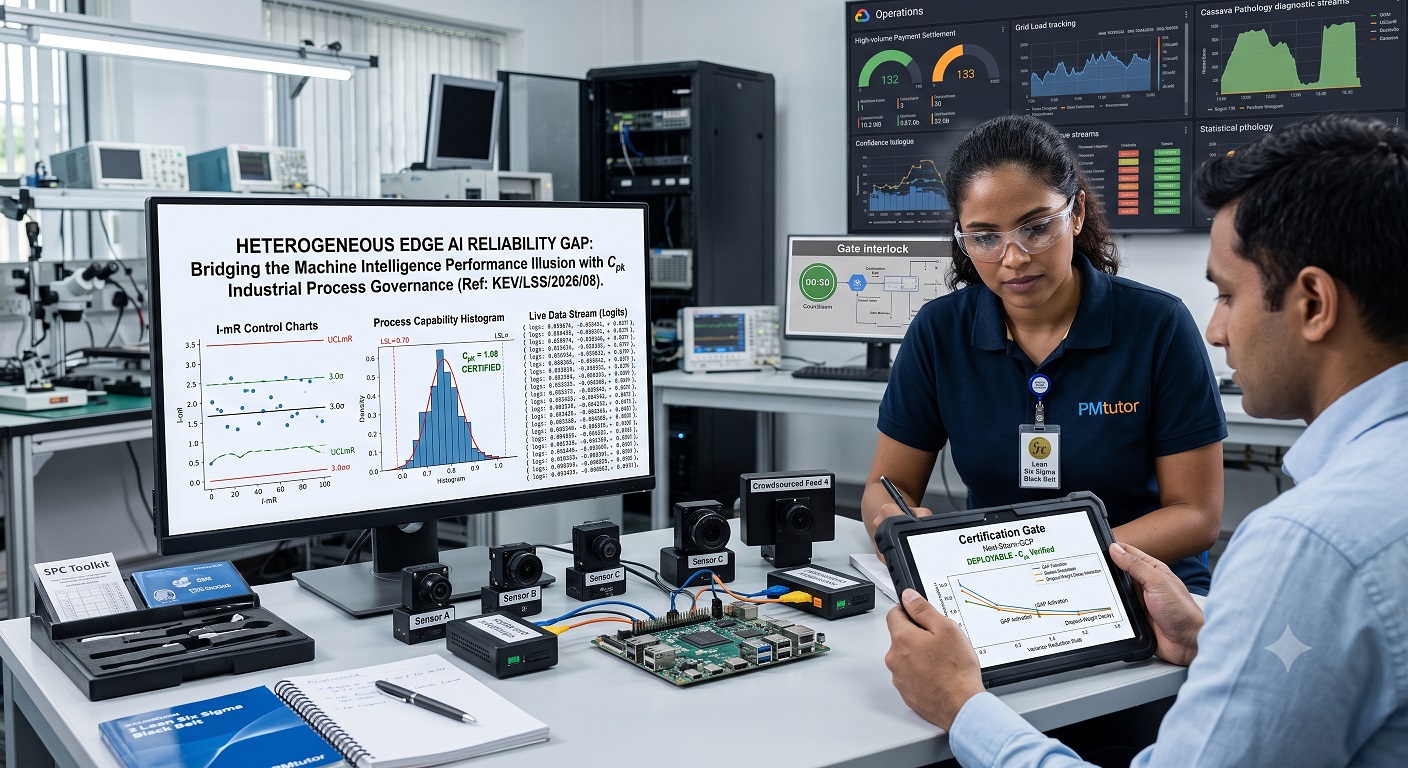
A CNN that hits 96% accuracy in the lab routinely fails in the field. This gap between validation and deployment is not a dataset problem. It’s a process problem.
When you move a trained model to edge hardware across different camera sensors and lighting conditions, aggregate accuracy numbers stop being predictive. The model performance becomes unstable. High variance. Unreliable.
The fix is to stop treating model inference as a black box that gets evaluated once, and start treating it as a continuous manufacturing process. Use the same quality control methods that factories use: process capability indices, factorial experiments, and automated gates. This brief outlines how.
1. Why validation accuracy misleads
Validation metrics like Top-1 accuracy or Macro F₁ compute an average across a static test set. That single number hides localized, severe failures that occur once the model runs on heterogeneous hardware and real environmental conditions.
Three sources of variance destroy field reliability.
Hardware variation across camera modules
Different camera sensors have different Image Signal Processor (ISP) pipelines, color filter arrays (CFA), lens distortion profiles, and quantum efficiency curves. Feed the same leaf image to five different camera modules, and you get five different pixel arrays going into the CNN. The model wasn’t trained to handle that level of ISP diversity.
Environmental noise and temporal drift
Ambient lighting shifts from dawn to dusk, atmospheric scattering changes with weather, and seasonal variations alter the visual signature of disease progression. A model trained on clean, balanced day-time images collapses under low-light conditions or after weeks of deployment when gradual sensor degradation compounds.
Why standard fixes don’t work at the edge
Localized fine-tuning adds latency. Massive data augmentation inflates model size. Multi-stage Transformers or adversarial alignment loops require compute and power that edge devices don’t have. Heavy architectures fail on embedded hardware. The problem isn’t technology. It’s that the current solutions break the constraints of edge deployment.
2. Reframe inference as a manufacturing process
Manufacturing quality control works because it stops treating production as binary (pass or fail) and instead measures the spread of output around a target. The key is statistical process capability.
For a deep learning model, the output characteristic X is the softmax confidence score, a continuous value between 0.0 and 1.0 that represents the model’s certainty in its prediction.
Define acceptable boundaries
Upper Specification Limit (USL): 1.0. Absolute certainty (theoretical).
Lower Specification Limit (LSL): 0.70. The minimum certainty threshold below which an automated decision should not execute without human review.
Measure the process spread
Deploy the baseline model across 30 heterogeneous camera modules under various illumination conditions. Collect confidence scores for all predictions. Calculate the mean (μ), standard deviation (σ), and process capability index (Cpk). This tells you how tightly grouped the predictions are relative to your acceptable window.
3. The mathematics of process capability
Process Capability Index (Cp)
Cp = (USL − LSL) / (6σ)
This measures the potential spread of the process against the specification width. It assumes the process is centered. In reality, it often isn’t.
Realized Process Capability Index (Cpk)
Cpk = min( (USL − μ) / (3σ), (μ − LSL) / (3σ) )
This accounts for both process spread and centering. It’s the one that matters in practice. If Cpk falls below 1.0, the process is statistically incapable of staying within specification limits. For autonomous edge deployment, that’s a red flag. The model should not be deployed without intervention.
4. DMAIC-GML: The governance protocol
| Phase | Action |
| Define | Establish the quality characteristic (LSL=0.70, USL=1.0). Lock the specification bounds. |
| Measure | Deploy across 30 heterogeneous sensors. Compute baseline μ, σ, and Cpk. |
| Analyze | Run 2³ Full Factorial DOE. Test input resolution, quantization depth, and layer configurations. |
| Improve | Lock optimal factor interactions to minimize variance. Stabilize feature representations against ISP noise. |
| Control | Deploy automated certification gate in GCP. Block deployment if Cpk < 1.0. |
Define phase
Quantify what reliable output looks like. Set LSL at 0.70 confidence: predictions below this threshold are uncertain enough to require human review. USL stays at 1.0 (theoretical perfect confidence). Lock these bounds.
Measure phase
Take the baseline MobileNetV2 model and run inference across 30 real camera modules with varying ISP configurations. Run the same test under different illumination profiles (dawn, noon, dusk, low-light). Collect all confidence scores. Compute μ and σ. Calculate Cpk.
Analyze phase: 2³ Full Factorial Design of Experiments
Test three factors at two levels each, measuring how they interact to reduce variance.
Factor A: Input resolution scaling (224×224 vs. 384×384)
Factor B: Post-training quantization depth (8-bit integer vs. 16-bit floating point)
Factor C: Structural configuration (Global Average Pooling alone vs. combined dropout and weight decay)
Run fixed-effects ANOVA on each combination across the 30-sensor baseline. Identify main effects and interaction terms. The interaction between quantization depth and layer configuration often suppresses variance across heterogeneous ISP pipelines more effectively than either alone.
Improve phase
Lock the optimal factor combination. For example, 16-bit quantization combined with dropout and weight decay typically stabilizes feature representations and reduces run-to-run variability when inference crosses different camera modules. Retrain or fine-tune the model with these settings locked in. Measure the new Cpk.
Control phase
Deploy an automated certification gate within the GCP CI/CD pipeline. At inference time, dynamically calculate Cpk across incoming prediction streams. If capability drops below 1.0 (falls below 3.0σ from specification center), the gate flags the model as unstable and blocks deployment until a new trained model passes recertification.
5. Operational implications
Stop optimizing for a single accuracy number. Accuracy alone doesn’t predict stability.
Standardize your model evaluation process. Treat model training and deployment as an auditable, repeatable manufacturing process with statistical bounds, not a trial-and-error search.
Automate quality gates. Embed Cpk certification checks into your deployment pipeline. Let the system reject models that don’t meet statistical capability thresholds, without waiting for field failures to reveal the problem.
Scale edge deployments with confidence. When a model passes Cpk certification across heterogeneous hardware, you’ve moved from hoping it works to proving it’s statistically bounded and reproducible.
